Orbit
 Xstreami

- About
- Services
- Blogs
- Careers
- Products
- Contact Schedule a Call
A MariaDB Galera cluster can experience severe stalls when concurrent updates to the same primary key trigger an unexpected deadlock issue. This blog explains how we reproduced the issue in MariaDB 10.2, why the affected node became unresponsive, and the recovery and upgrade options used to resolve it.
sukan September 10, 2026

Our setup has a three-node MariaDB Galera cluster running with 10.2.5 version, our cluster is serving reads and writes on all the three nodes. All our nodes have same hardware specification and application hits are split equally on these servers using ProxySQL. While everything is working fine, suddenly all the queries hang on random nodes and eventually the cluster stalls. Even though we have all deadlock detection mechanisms and other timeout settings, still cluster hangs and it brings the entire application down.
We have observed this behavior when we upgraded from MariaDB 10.1 to 10.2 and this bug is highly unpredictable. Even in low peak time with very minimal hits, we have faced this issue. The only option we had at the moment is to trigger an alert when we hit the error and schedule a shell script to force restart the affected node
After detailed study of the environment, queries, hits etc we were able to reproduce this bug.
Consider the below table used to store youtubeviews status for different services.
Table Structure
CREATE TABLE `youtube_views` ( `id` int NOT NULL AUTO_INCREMENT, `status` int NOT NULL, `token_id` varchar(50) DEFAULT NULL, `session_id` varchar(50) DEFAULT NULL, `response` int DEFAULT NULL, PRIMARY KEY (`id`)) ENGINE=InnoDB DEFAULT CHARSET=latin1;Table Data
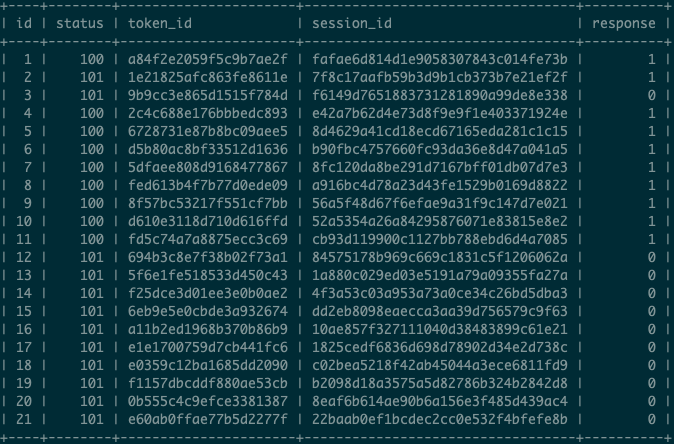
status column is being changed every time. Thus having the possibility to fire multiple updates for the same ID column [Primary key]
+---------+-------------+-----------+------+---------+-------+---------------------------------------+------------------------------------------------+----------+| Id | User | Host | db | Command | Time | State | Info | Progress |+---------+-------------+-----------+------+---------+-------+---------------------------------------+------------------------------------------------+----------+| 1 | system user | | NULL | Sleep | 1495 | Update_rows_log_event::find_row(2630) | update youtubeviews set status=100 where id=5 | 0.000 || 2 | system user | | NULL | Sleep | 73330 | wsrep aborter idle | NULL | 0.000 || 1052481 | root | localhost | prod | Query | 1496 | query end | update youtubeviews set status=100 where id=5 | 0.000 || 1052973 | root | localhost | prod | Killed | 924 | query end | update youtubeviews set status=101 where id=11 | 0.000 || 1052974 | root | localhost | NULL | Sleep | 190 | | NULL | 0.000 || 1052980 | root | localhost | prod | Query | 0 | init | show processlist | 0.000 |+---------+-------------+-----------+------+---------+-------+---------------------------------------+------------------------------------------------+----------+You could see below error on the MariaDB error logs.
The first response from the DBA is to manually kill the query which has stalled the cluster. Unfortunately this bug is so worse that killing the query doesn’t bring up the cluster; in fact we will not able to restart of node as well.
One has to manually kill the affected MariaDB Cluster node and force restarting would help bringing back the cluster online.
Running Galera Cluster in a single node
We have put the Galera cluster writes in to a single node and keep other nodes for reads. Having said that it would avoid hitting this error but again it is more or less similar to normal Master / Slave MariaDB.
Upgrade the cluster to 10.2.13+ version
As rightly pointed out by MariaDB in their release notes, upgrading cluster to 10.2.13 version is highly recommended as they have provided the fix for this bug. [MDEV-12837]
The same test was applied to this newer version, understandingly when we fire updates for the same ID in different nodes below error is thrown and transaction gets rollbacked.
Cannot run query update youtubeviews set status=100 where id=5; ERROR : Deadlock: wsrep aborted transactionNOTE: Since applications are connected to Galera cluster via ProxySQL, a rolling restart is all need for upgrading the cluster.
As such cases, where upgradation not possible, downgrading the cluster to 10.1 can avoid from this bug. As in this 10.1 version, it immediately thrown an deadlock error once it hit this situation.
This issue showed how an unpredictable Galera bug can bring down an entire application even when timeout and deadlock protections are already in place. After reproducing the problem, we found that upgrading to MariaDB 10.2.13+ resolved the issue, while routing writes through a single node provided an alternative workaround.
At Mafiree, we help businesses troubleshoot and optimize high-availability database environments, including MariaDB Galera clusters. From identifying replication issues to resolving unexpected cluster failures, our focus is on keeping production databases stable, reliable, and available.
good article, nice information, thanks for your knowlwdge sharing.
More than 6000 Servers Monitored
Happy Clients
Certified DBAs
24 x 7 x 365 Support


Miru IT Park, Vallankumaranvillai,
Nagercoil, Tamilnadu - 629 002.
Unit 303, Vanguard Rise,
5th Main, Konena Agrahara,
Old Airport Road, Bangalore - 560 017.
Call: +91 6383016411
Email: sales@mafiree.com