Mafiree logo
  • About
  • Services
  • Blogs
  • Careers
  • Products
    • orbit logo Orbit
    • streamer logo Xstreami
  • Contact
Schedule a Call
Menu
  • About
  • Services
  • Blogs
  • Careers
  • Products
    • orbit logo Orbit
    • streamer logo Xstreami
  • Contact
  • Schedule a Call
Database
Database Managed Database Services
MySQL MySQL
MySQL Consulting
MySQL Migration Services
MySQL Optimization & Query Tuning
MySQL Database Administration
MySQL Backup & Recovery
MySQL Security & Maintenance
MySQL Cloud Services (AWS RDS, Aurora, Google Cloud SQL, Azure)
MySQL for Ecommerce
MySQL High Availability & Replication
MongoDB MongoDB
MongoDB Consulting
MongoDB Migration Services
MongoDB Optimization & Query Tuning
MongoDB Database Administration
MongoDB Backup & Recovery
MongoDB Security & Maintenance
MongoDB Cloud (Atlas)
MongoDB Solutions by Industry
MongoDB High Availability & Replication
PostgreSQL PostgreSQL
PostgreSQL Consulting
PostgreSQL Migration & Upgrades
Performance Tuning & Query Optimization
PostgreSQL Administration & Managed Services
High Availability, Clustering & Replication
PostgreSQL Backup, Recovery & Disaster Planning
PostgreSQL Security, Compliance & Auditing
PostgreSQL for Analytics & Data Warehousing
PostgreSQL on Cloud & Containers
PostgreSQL Extensions & Open-Source Integrations
PostgreSQL for Every Industry
SQL Server MSSQL
MSSQL Consulting
MSSQL Migration Services
MSSQL Optimization & Query Tuning Services
MSSQL Database Administration Services
MSSQL Backup & Recovery Services
MSSQL High Availability & Replication Services
MSSQL Security & Compliance Services
MSSQL Performance Monitoring & Health Checks
MSSQL Solutions by Industry
Aerospike Aerospike
Aerospike Consulting
Aerospike Migration Services
Aerospike Performance Optimization & Tuning
Aerospike Backup & Recovery
Aerospike High Availability
Aerospike Cloud & Hybrid Deployments
Aerospike for Real-Time Applications (AdTech, FinTech, Retail, IoT)
Clickhouse Clickhouse
ClickHouse Consulting
ClickHouse Migration Services
ClickHouse Optimization & Query Tuning
ClickHouse Database Administration
ClickHouse Backup & Recovery
ClickHouse Security & Maintenance
ClickHouse Cloud Services (ClickHouse Cloud, AWS, GCP, Azure)
ClickHouse Solutions by Industry
ClickHouse High Availability & Replication
TiDB TiDB
TiDB Consulting
TiDB Administration & Maintenance
TiDB Security and Privacy Maintenance
TiDB Performance & Query Optimization
TiDB Migration Services
TiDB Backup & Disaster Recovery
TiDB High Availability Solutions
TiDB Solutions by Industry
TiDB Cloud Services
ScyllaDB ScyllaDB
ScyllaDB Consulting
ScyllaDB Administration & Maintenance
ScyllaDB Security and Privacy Maintenance
ScyllaDB Performance & Query Optimization
ScyllaDB Migration Services
ScyllaDB Backup & Disaster Recovery
ScyllaDB High Availability Solutions
ScyllaDB Solutions by Industry
ScyllaDB Cloud Services
DevOps
DevOps DevOps Services
Version Control Version Control
Kubernetes Kubernetes
Infrastructure Infrastructure Management
Web Servers Web Servers
Networking
Networking Networking Services
Basic Basic
Advanced Advanced
MySQL MySQL
MongoDB MongoDB
PostgreSQL PostgreSQL
MSSQL MSSQL
Aerospike Aerospike
Clickhouse Clickhouse
TiDB TiDB
ScyllaDB ScyllaDB
Version Control Version Control
Kubernetes Kubernetes
Infrastructure Infrastructure Management
Web Servers Web Servers
Basic Basic
Advanced Advanced
MySQL Consulting
MySQL Migration Services
MySQL Optimization & Query Tuning
MySQL Database Administration
MySQL Backup & Recovery
MySQL Security & Maintenance
MySQL Cloud Services (AWS RDS, Aurora, Google Cloud SQL, Azure)
MySQL for Ecommerce
MySQL High Availability & Replication
MongoDB Consulting
MongoDB Migration Services
MongoDB Optimization & Query Tuning
MongoDB Database Administration
MongoDB Backup & Recovery
MongoDB Security & Maintenance
MongoDB Cloud (Atlas)
MongoDB Solutions by Industry
MongoDB High Availability & Replication
PostgreSQL Consulting
PostgreSQL Migration & Upgrades
Performance Tuning & Query Optimization
PostgreSQL Administration & Managed Services
High Availability, Clustering & Replication
PostgreSQL Backup, Recovery & Disaster Planning
PostgreSQL Security, Compliance & Auditing
PostgreSQL for Analytics & Data Warehousing
PostgreSQL on Cloud & Containers
PostgreSQL Extensions & Open-Source Integrations
PostgreSQL for Every Industry
MSSQL Consulting
MSSQL Migration Services
MSSQL Optimization & Query Tuning Services
MSSQL Database Administration Services
MSSQL Backup & Recovery Services
MSSQL High Availability & Replication Services
MSSQL Security & Compliance Services
MSSQL Performance Monitoring & Health Checks
MSSQL Solutions by Industry
Aerospike Consulting
Aerospike Migration Services
Aerospike Performance Optimization & Tuning
Aerospike Backup & Recovery
Aerospike High Availability
Aerospike Cloud & Hybrid Deployments
Aerospike for Real-Time Applications (AdTech, FinTech, Retail, IoT)
ClickHouse Consulting
ClickHouse Migration Services
ClickHouse Optimization & Query Tuning
ClickHouse Database Administration
ClickHouse Backup & Recovery
ClickHouse Security & Maintenance
ClickHouse Cloud Services (ClickHouse Cloud, AWS, GCP, Azure)
ClickHouse Solutions by Industry
ClickHouse High Availability & Replication
TiDB Consulting
TiDB Administration & Maintenance
TiDB Security and Privacy Maintenance
TiDB Performance & Query Optimization
TiDB Migration Services
TiDB Backup & Disaster Recovery
TiDB High Availability Solutions
TiDB Solutions by Industry
TiDB Cloud Services
ScyllaDB Consulting
ScyllaDB Administration & Maintenance
ScyllaDB Security and Privacy Maintenance
ScyllaDB Performance & Query Optimization
ScyllaDB Migration Services
ScyllaDB Backup & Disaster Recovery
ScyllaDB High Availability Solutions
ScyllaDB Solutions by Industry
ScyllaDB Cloud Services
  1. Home
  2. > Blogs
  3. > PostgreSQL
  4. > 8 Enhancing Features in PostgreSQL 18

8 Enhancing Features in PostgreSQL 18

PostgreSQL 18: Efficiency, security, and reliability, all in one upgrade

Jethish September 10, 2026

Subscribe for email updates

Summarize with AI: ChatGPT Google AI Perplexity Claude Grok


What’s New in PostgreSQL 18?

PostgreSQL 18 continues the database’s reputation as one of the most advanced open-source relational database systems available today. This release improves performance for both OLTP and analytics workloads while simplifying application development and database administration.


Why PostgreSQL 18 Is a Significant Release

The focus areas of PostgreSQL 18 include:

  • Improved storage and query performance
  • Better indexing intelligence
  • Enhanced upgrade experience
  • Modern authentication standards
  • Stronger temporal data integrity
  • Developer-friendly SQL enhancement

PostgreSQL 18 Async I/O — Faster Disk Reads Up to 3x

One of the most important PostgreSQL 18 features is the introduction of Asynchronous I/O (AIO).

PostgreSQL can now perform non-blocking disk operations for:

  • Sequential scans
  • Bitmap heap scans
  • VACUUM operations

Instead of waiting for disk reads to complete, PostgreSQL processes requests asynchronously, significantly improving throughput and reducing latency.


How to Configure io_method in postgresql.conf

PostgreSQL 18 introduces new asynchronous I/O settings that can be configured directly inside postgresql.conf.


io_method = worker


Depending on the operating system and workload, administrators can tune I/O behavior for better concurrency and performance.


Index Skip Scan Improvements

Another major enhancement is PostgreSQL 18 Skip Scan, which improves how PostgreSQL uses multicolumn B-tree indexes.

Previously, composite indexes were only fully useful when queries filtered on the leading column. PostgreSQL 18 now allows the planner to intelligently skip unused portions of an index.


psql — miru_sports
--- Index with 3 columns
miru_sports=# CREATE INDEX idx_sports_stats ON sports_stats (league, team, match_date);
CREATE INDEX

--- filter is omitted but the index still works
miru_sports=# EXPLAIN SELECT team FROM sports_stats
               WHERE team = 'Team 5'
                 AND match_date BETWEEN '2025-06-01' AND '2025-08-31';

                                        QUERY PLAN
------------------------------------------------------------------------------------------------------------
 Index Only Scan using idx_sports_stats on sports_stats
   (cost=0.29..27.17 rows=635 width=7)
   (actual time=0.088..0.203 rows=616.00 loops=1)
 Index Cond: (
   (team = 'Team 5'::text)
   AND (match_date >= '2025-06-01'::date)
   AND (match_date <= '2025-08-31'::date)
 )


--- Index with 3 columns
miru_sports=# CREATE INDEX idx_sports_stats ON sports_stats (league, team, match_date);
CREATE INDEX
 

Even without filtering on league, PostgreSQL can still efficiently use the index:


--- filter is ommitted but the index still works
miru_sports=# EXPLAIN SELECT team FROM sports_stats WHERE team = ‘Team 5’ AND match_date BETWEEN '2025-06-01' AND '2025-08-31';
QUERY PLAN 
--------------------------------------------------------------------------------------------------------------------------------------------
Index Only Scan using idx_sports_stats on sports_stats (cost=0.29..27.17 rows=635 width=7) (actual time=0.088..0.203 rows=616.00 loops=1)
Index Cond: ((team = 'Team 5'::text) AND (match_date >= '2025-06-01'::date) AND (match_date <= '2025-08-31'::date))


How Skip Scan Reduces Query Cost on Composite Indexes

Benefits include:

  • Better utilization of existing indexes
  • Reduced need for duplicate indexes
  • Lower storage overhead
  • Fewer full table scans
  • Faster query execution plans

This is especially beneficial for applications with large and complex indexing strategies.


Native UUIDv7 Support in PostgreSQL 18

PostgreSQL UUIDv7 support is now built directly into PostgreSQL 18.

Traditional random UUIDs (UUIDv4) often cause index fragmentation because inserted values are randomly distributed. UUIDv7 solves this by generating time-ordered UUIDs.


psql — postgres
postgres=# CREATE TABLE events (
             id         UUID        PRIMARY KEY DEFAULT uuidv7(),
             event_time TIMESTAMPTZ DEFAULT now(),
             payload    TEXT
           );
CREATE TABLE
psql — postgres
-- Inspect the timestamp
postgres=# SELECT id, event_time, payload, uuid_extract_timestamp(id)
           FROM events;

                 id                   |         event_time           |     payload      |   uuid_extract_timestamp   
--------------------------------------+------------------------------+------------------+----------------------------
 019984f4-f912-7359-a149-cc772e50f682 | 2025-09-26 07:37:51.122+00 | user_login       | 2025-09-26 07:37:51.122+00
 019984f4-f912-7896-a803-7fd9494e3d76 | 2025-09-26 07:37:51.122+00 | order_created    | 2025-09-26 07:37:51.122+00
 019984f4-f912-78d5-8639-09d8e418a6cd | 2025-09-26 07:37:51.122+00 | payment_received | 2025-09-26 07:37:51.122+00
 019984f4-f912-78ef-a145-d0251338fec6 | 2025-09-26 07:37:51.122+00 | order_shipped    | 2025-09-26 07:37:51.122+00
(4 rows)


psql — postgres
postgres=# CREATE TABLE events (
             id         UUID        PRIMARY KEY DEFAULT uuidv7(),
             event_time TIMESTAMPTZ DEFAULT now(),
             payload    TEXT
           );
CREATE TABLE
psql — postgres
-- Inspect the timestamp
postgres=# SELECT id, event_time, payload, uuid_extract_timestamp(id)
           FROM events;

                 id                   |         event_time           |     payload      |   uuid_extract_timestamp   
--------------------------------------+------------------------------+------------------+----------------------------
 019984f4-f912-7359-a149-cc772e50f682 | 2025-09-26 07:37:51.122+00 | user_login       | 2025-09-26 07:37:51.122+00
 019984f4-f912-7896-a803-7fd9494e3d76 | 2025-09-26 07:37:51.122+00 | order_created    | 2025-09-26 07:37:51.122+00
 019984f4-f912-78d5-8639-09d8e418a6cd | 2025-09-26 07:37:51.122+00 | payment_received | 2025-09-26 07:37:51.122+00
 019984f4-f912-78ef-a145-d0251338fec6 | 2025-09-26 07:37:51.122+00 | order_shipped    | 2025-09-26 07:37:51.122+00
(4 rows)


CREATE TABLE events (
id UUID PRIMARY KEY DEFAULT uuidv7(),
event_time TIMESTAMPTZ DEFAULT now(),
payload TEXT
);


Inspect the timestamp

postgres=# SELECT id,event_time,payload,uuid_extract_timestamp(id) from events;
id | event_time | payload | uuid_extract_timestamp 
--------------------------------------+-------------------------------+------------------+----------------------------
019984f4-f912-7359-a149-cc772e50f682 | 2025-09-26 07:37:51.122+00 | user_login | 2025-09-26 07:37:51.122+00
019984f4-f912-7896-a803-7fd9494e3d76 | 2025-09-26 07:37:51.122+00 | order_created | 2025-09-26 07:37:51.122+00
019984f4-f912-78d5-8639-09d8e418a6cd | 2025-09-26 07:37:51.122+00 | payment_received | 2025-09-26 07:37:51.122+00
019984f4-f912-78ef-a145-d0251338fec6 | 2025-09-26 07:37:51.122+00 | order_shipped | 2025-09-26 07:37:51.122+00


UUIDv7 vs UUIDv4: Why the Switch Matters

UUIDv7 offers several advantages over UUIDv4:

  • Better index locality
  • Reduced page splits
  • Improved insert performance
  • Better cache efficiency
  • More predictable storage behavior

Expanded RETURNING Support — With OLD and NEW

PostgreSQL 18 enhances the RETURNING clause by allowing direct access to OLD and NEW row values during:

  • INSERT
  • UPDATE
  • DELETE
  • MERGE

miru_sports=# UPDATE deliveries SET status = 'Delivered' WHERE delivery_id = 1 RETURNING OLD.*, NEW.*;
delivery_id | order_id | delivery_date | status | delivery_id | order_id | delivery_date | status 
-------------+----------+---------------+---------+-------------+----------+---------------+-----------
1 | 1 | 2025-09-28 | Pending | 1 | 1 | 2025-09-28 | Delivered
(1 row)
UPDATE 1


Impact

  • Cleaner auditing logic
  • Easier change tracking
  • Simplified application workflows
  • Reduced trigger complexity

Virtual Generated Columns

Generated columns in PostgreSQL 18 are now virtual by default, meaning values are computed during reads rather than stored physically.


CREATE TABLE shop_orders (
order_id SERIAL PRIMARY KEY,
product_name VARCHAR(50),
unit_price NUMERIC(7,2),
quantity INT,
total_price NUMERIC(9,2)
GENERATED ALWAYS AS (unit_price * quantity) VIRTUAL
);


Insert Sample Data:


miru_sports-# INSERT INTO shop_orders (product_name, unit_price, quantity) VALUES ('Football', 1500.00, 2), ('Cricket Bat', 2500.50, 1), ('Basketball', 1800.25, 3);
INSERT 0 3


Query example:


miru_sports=# SELECT order_id, product_name, unit_price, quantity, total_price FROM shop_orders;
order_id | product_name | unit_price | quantity | total_price 
----------+--------------+------------+----------+-------------
1 | Football | 1500.00 | 2 | 3000.00
2 | Cricket Bat | 2500.50 | 1 | 2500.50
3 | Basketball | 1800.25 | 3 | 5400.75
(3 rows)

Updating a record


miru_sports=# UPDATE shop_orders SET quantity = 4 WHERE product_name = 'Cricket Bat';
UPDATE 1

Always Up-to-Date


miru_sports=# SELECT order_id, product_name, unit_price, quantity, total_price
FROM shop_orders;
order_id | product_name | unit_price | quantity | total_price 
----------+--------------+------------+----------+-------------
1 | Football | 1500.00 | 2 | 3000.00
3 | Basketball | 1800.25 | 3 | 5400.75
2 | Cricket Bat | 2500.50 | 4 | 10002.00
(3 rows)


Benefits of Virtual Generated Columns

  • Reduced storage usage
  • Always up-to-date computed values
  • Simplified schema design
  • Useful for derived business attributes

Ideal Use Cases

  • Pricing calculations
  • Tax computations
  • Inventory summaries
  • Derived reporting fields

OAuth 2.0 Authentication in PostgreSQL 18

PostgreSQL 18 adds OAuth authentication support, allowing integration with identity providers (IdPs) for token-based authentication.


Benefits

  • Centralized authentication management
  • Improved security controls
  • Easier compliance management
  • Better cloud-native integration

Impact

Organizations using modern infrastructure can now standardize database authentication alongside application authentication workflows.


Temporal Constraints

PostgreSQL 18 introduces native temporal constraints for:

  • PRIMARY KEY
  • UNIQUE
  • FOREIGN KEY

This allows constraints to enforce validity across time ranges.


Example:-


--- create a table employee to demonstrate temporal constraints

CREATE TABLE employee (
emp_id INTEGER,
emp_name VARCHAR(100) NOT NULL,
department VARCHAR(50) NOT NULL,
position VARCHAR(50) NOT NULL,
salary DECIMAL(10,2) NOT NULL,
valid_period tstzrange NOT NULL DEFAULT tstzrange(now(), 'infinity', '[)'),
PRIMARY KEY (emp_id, valid_period WITHOUT OVERLAPS)
);

--- Insert data into the table
mafiree=# INSERT INTO employee (emp_id, emp_name, department, position, salary, valid_period)
VALUES
(1, 'Alice Johnson', 'Engineering', 'Software Engineer', 75000,
tstzrange('2024-01-01', '2025-01-01', '[)')),
(1, 'Alice Johnson', 'Engineering', 'Senior Software Engineer', 85000,
tstzrange('2025-01-01', 'infinity', '[)')),
(2, 'Bob Wilson', 'Marketing', 'Marketing Specialist', 60000,
tstzrange('2024-06-01', 'infinity', '[)'));
INSERT 0 3

// The temporal primary key (emp_id, valid_period WITHOUT OVERLAPS) allows multiple rows for the same employee (emp_id = 1) as long as their time periods don't overlap. This enables you to maintain a complete history of changes while ensuring data integrity. //


Benefits of Temporal Constraints

  • Prevents overlapping time ranges
  • Maintains historical integrity
  • Simplifies application logic
  • Reduces dependency on triggers

Ideal Use Cases

  • HR systems
  • Financial applications
  • Subscription management
  • Insurance platforms
  • Audit history tracking

pg_upgrade Retains Optimizer Statistics

A major operational improvement in PostgreSQL 18 upgrade workflows is that pg_upgrade now retains optimizer statistics.

Previously, DBAs often needed to rebuild statistics after upgrades, which could impact performance immediately after migration.

Benefits

  • Faster upgrade completion
  • Reduced downtime
  • Stable post-upgrade performance
  • Faster production cutovers

This is especially valuable for large enterprise databases where ANALYZE operations can take significant time.


Should You Upgrade to PostgreSQL 18? A DBA’s Checklist

For most organizations, PostgreSQL 18 offers meaningful benefits in:

  • Performance
  • Scalability
  • Security
  • Operational simplicity

Breaking Changes to Review Before Upgrading

Before upgrading:

  • Review extension compatibility
  • Validate replication configurations
  • Test authentication changes
  • Benchmark application workloads
  • Review deprecated configuration parameters

Recommended Upgrade Path

Recommended best practices:

  1. Test upgrades in staging environments
  2. Validate backup and rollback plans
  3. Benchmark critical queries
  4. Use pg_upgrade for minimal downtime migrations
  5. Monitor workloads post-upgrade


FAQ

Yes. PostgreSQL 18 is designed for enterprise production workloads with major improvements in performance, replication, and security.
Many DBAs consider Async I/O and Skip Scan among the most impactful performance improvements.
Yes. PostgreSQL 18 introduces native support for UUIDv7 generation and timestamp extraction.
Absolutely. OAuth integration simplifies centralized authentication and aligns PostgreSQL with modern enterprise security practices.
Yes. PostgreSQL 18 retains optimizer statistics during pg_upgrade, significantly reducing post-upgrade tuning effort.

Author Bio

Jethish

Jethish is a PostgreSQL DBA at Mafiree with expertise in building scalable, reliable, and high-performance database infrastructures. He focuses on PostgreSQL architecture, replication strategies, performance tuning, and high availability for mission-critical systems. Through his technical writing, he shares clear, practical insights on database internals, replication choices, load balancing, and cross-database integrations that help engineers and DBAs tackle real-world data challenges.

Leave a Comment

Related Blogs

PostgreSQL Replication Setup: Step-by-Step Guide for Streaming Replication and Failover

Understand how PostgreSQL streaming replication works, deploy a primary server and replica node, implement failover for high availability, and optimize your replication setup with Mafiree's expert DBA services. Ensuring high availability and data protection in PostgreSQL environments is critical for modern applications. One of the most effective ways to achieve this is through PostgreSQL replication setup, particularly using streaming replication with failover capabilities. This guide walks you through configuring a robust PostgreSQL replication system, covering everything from basic setup to handling failover scenarios.

  45 views
REPACK in PostgreSQL 19: Finally, Online Table Bloat Removal in Core

PostgreSQL 19 introduces REPACK, a native command that unifies the functionality of VACUUM FULL and CLUSTER while adding support for CONCURRENTLY to minimize downtime. Unlike traditional table rewrites that require long ACCESS EXCLUSIVE locks, REPACK can reclaim table bloat online by copying live data, rebuilding indexes, and applying concurrent changes before a final metadata swap. This article explores how REPACK works internally, compares it with VACUUM FULL and pg_repack, demonstrates a hands-on performance test, explains the new pg_stat_progress_repack monitoring view, and covers current limitations and best practices for production environments.

  13226 views
ProxySQL vs HAProxy for MySQL High Availability: Complete Comparison 2026

ProxySQL excels in MySQL-specific query routing, read/write splitting, and performance tuning. HAProxy offers robust load balancing across multiple protocols and is ideal for general-purpose proxying. Choose ProxySQL if your focus is on MySQL optimization; select HAProxy for broader application-level load balancing. Both tools support failover mechanisms but with different levels of database-specific integration.

  348 views
Tracking PostgreSQL Operations in Real Time: A Deep Dive into PostgreSQL Progress Reporting

This blog explores PostgreSQL’s progress reporting system views that provide real-time visibility into long-running operations like VACUUM, ANALYZE, CREATE INDEX, COPY, and base backups. It explains how DBAs can monitor execution phases, estimate completion, detect bottlenecks, and improve operational efficiency using these built-in views. Real-world examples and use cases demonstrate how progress tracking enhances performance tuning, automation, and maintenance planning.

  13156 views
Key Differences Between MySQL and PostgreSQL: Architecture, Performance & Use Cases

Understanding the difference between MySQL and PostgreSQL is critical when choosing a database for production workloads. While both are powerful open-source relational databases, they are built with fundamentally different philosophies. This comprehensive guide compares MySQL vs PostgreSQL across architecture, performance behavior under concurrent loads, replication strategies, and real-world use cases — backed by Mafiree's 17+ years of hands-on production experience across India, APAC, and the Middle East.

  1261 views
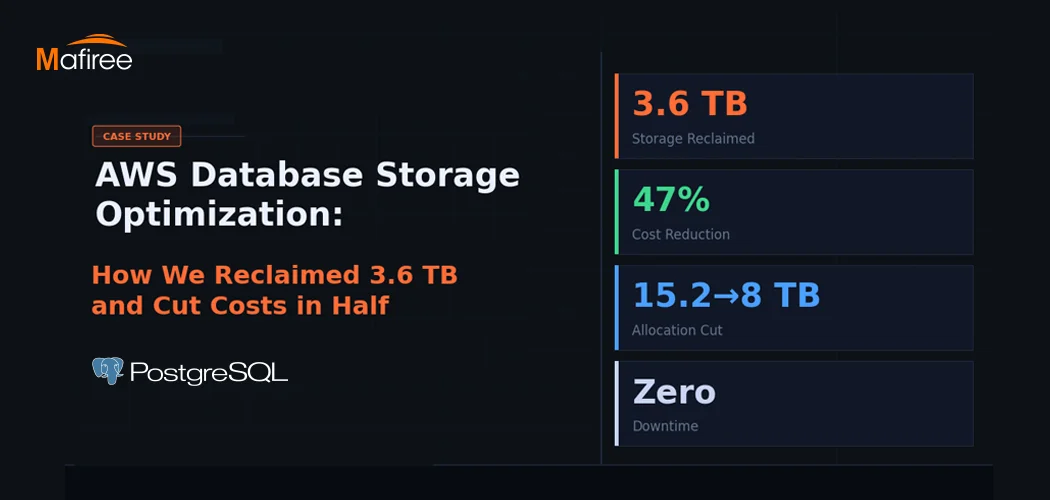
AWS Database Storage Optimization: How We Reclaimed 3.6 TB and Cut Costs in Half

A client came to us with a classic AWS database storage optimization problem: 15.2 TB allocated, less than a third actually in use — and a bill that kept growing regardless. Within one week, Mafiree had reclaimed 3.6 TB, validated a safe path to cut allocation nearly in half, and executed a zero-downtime migration. Here's the full story.

  923 views
PostgreSQL Connection Pooling: PgBouncer vs Odyssey – Performance & Configuration

PostgreSQL uses a process-per-connection model, which can limit scalability in high-traffic environments. Connection poolers help manage this challenge by reusing database connections efficiently. This blog compares PgBouncer and Odyssey, two popular PostgreSQL connection poolers, highlighting their architecture, performance characteristics, configuration differences, and ideal use cases. It helps organizations choose the right pooling solution based on workload scale, complexity, and operational requirements.

  7492 views
Optimizing PostgreSQL Queries with Functional Indexes – A Real-World Case Study

Cutting Query Time from 10 Minutes to Under 1 Second – How Functional Indexes Helped Us Optimize Aurora PostgreSQL and Stabilize CPU Performance.

  4447 views
Mastering PostgreSQL Meta-Commands: The Ultimate psql Cheat Sheet

Why memorize SQL queries when \d, \l, and \dx do the heavy lifting? Learn the power of PostgreSQL’s psql meta-commands today.

  5091 views
Choosing the Right Replication Type in PostgreSQL

Choosing the Right Replication Type in PostgreSQL – Understand the key differences between Streaming and Logical Replication, their best use cases, and how to implement them effectively for high availability, scalability, and disaster recovery.

  3775 views
PostgreSQL Schema Changes pg_osc: Zero-Downtime Migrations for Production Systems

Altering large tables in PostgreSQL can cause locks, performance issues, and downtime in production environments. This blog explains how pg_osc (PostgreSQL Online Schema Change) enables safe schema modifications using a shadow table approach, allowing applications to continue operating during migrations. The article covers how pg_osc works, compares it with alternatives like pg_repack, explores real-world use cases, and provides practical steps for implementing online schema changes in production. It also highlights best practices used by Mafiree to perform reliable zero-downtime PostgreSQL schema migrations in high-traffic environments.

  3147 views
Connecting MySQL to PostgreSQL Using mysql_fdw for Cross-DB Queries

This illustration represents the power of mysql_fdw in enabling smooth data exchange and real-time connectivity between MySQL and PostgreSQL. A perfect solution for cross-database operations and data integration!

  4617 views
Incremental Backup In PostgreSQL 17

Revolutionize your database management with PostgreSQL 17! Experience faster, smarter, and more efficient backups with the power of incremental backup. Reduce storage, save time, and ensure seamless recovery – the future of PostgreSQL backup starts here!

  1285 views
A Practical Guide to PostgreSQL Load Balancing

Load balancing in PostgreSQL distributes client connections across multiple database servers to improve performance, scalability, and availability. This guide compares Pgpool-II, ProxySQL, and HAProxy, covering their key features, advantages, limitations, and suitability for PostgreSQL workloads.

  13145 views
7 Enhancing Features In PostgreSQL 17

PostgreSQL 17 is here to revolutionize your database experience! Packed with enhanced performance, cutting-edge features, and improved scalability, this release is designed to meet the evolving demands of modern applications. Whether you're handling complex queries or scaling to new heights, PostgreSQL 17 brings unparalleled reliability and efficiency to your data management solutions.

  3657 views
6 Interesting Features in PostgreSQL 16

Recently Postgres 16 has launched and I have picked the most interesting feature in this blog.

  5583 views
PostgreSQL Autovacuum Explained in Detail

This blog explains how PostgreSQL Autovacuum works — covering the launcher/worker process model, the exact formula that decides when a table becomes eligible, and the key differences between VACUUM, Autovacuum, and VACUUM FULL. It includes an interactive eligibility calculator, tunable parameters, monitoring queries, and best practices to help DBAs prevent table bloat and transaction ID wraparound.

  1766 views

Subscribe for email updates

Get in touch with us

Highlights

More than 6000 Servers Monitored

Happy Clients

Certified DBAs

24 x 7 x 365 Support

PCI

Database Services

MySQL MongoDB PostgreSQL SQL Server Aerospike Clickhouse TiDB ScyllaDB

Quick Links

Careers Blog Contact Privacy Policy Disclaimer Policy

Contacts

Linkedin Mafiree Facebook Mafiree Twitter Mafiree

Nagercoil Office

Miru IT Park, Vallankumaranvillai,

Nagercoil, Tamilnadu - 629 002.

Bangalore Office

Unit 303, Vanguard Rise,

5th Main, Konena Agrahara,

Old Airport Road, Bangalore - 560 017.

Call: +91 6383016411

Email: sales@mafiree.com


Copyright © - All Rights Reserved - Mafiree